Distributed Lock with Redis - Critique
Table of Contents
TL;DR: Redis is an AP system, not a CP system. It cannot guarantee strong consistency. For high-concurrency use cases, expect potential data races when using Redis. Consider systems that provide strong consistency (e.g., etcd, ZooKeeper) if you need strict guarantees.
The Single-Instance Lock⌗
In the previous post, we explored how to implement a distributed lock using a single Redis instance. We addressed the question: what if the client crashes? But we left one critical question unanswered: what if Redis itself fails?
This post examines that question and why the answer is more nuanced than you might expect.
Redis is an AP System⌗
If you’re unfamiliar with what an AP system means in the context of the CAP theorem, you can read my article here.
In short, an AP system prioritizes availability over data consistency across multiple nodes. When a failure occurs (e.g., network partition, node crash), the system remains available but may serve stale or inconsistent data.
Redis uses asynchronous replication by default in a primary-replica architecture. This means writes acknowledged by the primary are not guaranteed to be replicated to replicas before the acknowledgment is sent to the client.
Here’s the problem for distributed locks: if the Redis primary crashes after acknowledging a lock acquisition but before replicating it, a replica promoted to primary won’t have the lock data. Another client could then acquire the same lock, violating mutual exclusion. While Redis has mechanisms to resync data after failover, the newly promoted primary may still operate on stale state during this window.

The Split-Brain Problem⌗
Even with multiple Redis instances and the Redlock algorithm, another fundamental issue remains: split-brain.
Consider this scenario: Client A acquires a lock and begins processing. Then it gets paused, perhaps due to a long garbage collection (GC) pause, a VM suspension, or network latency. While paused, no lock extension happens, and the lock’s TTL expires. Client B now acquires the same lock and starts working on the shared resource. When Client A eventually resumes, it has no idea its lock expired and continues operating as if it still holds exclusive access.
Both clients are now modifying the same resource simultaneously. This is a classic split-brain scenario: two processes believe they have exclusive access, but neither actually does.
Martin Kleppmann explored this problem in depth in How to do distributed locking. His key insight is that Redlock makes dangerous assumptions about timing: bounded network delays, bounded process pauses, and bounded clock error. Distributed systems regularly violate these assumptions.
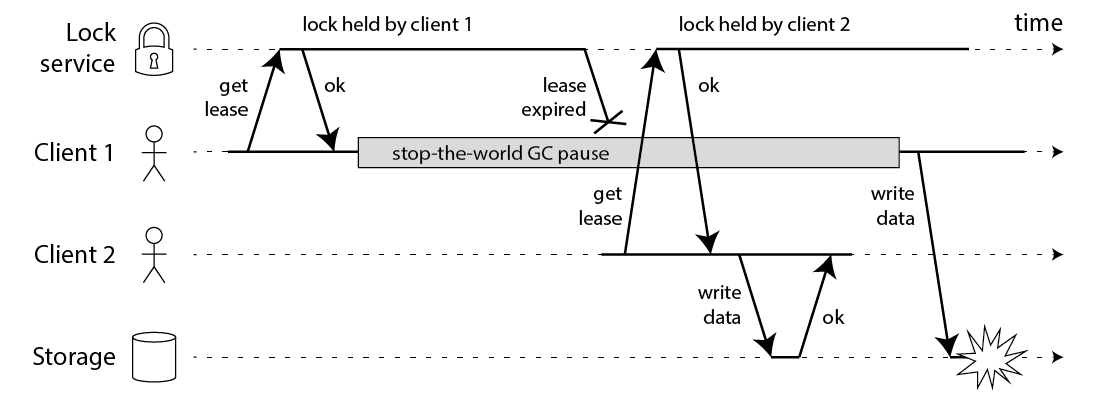
Image credit: Martin Kleppmann
Kleppmann recommends fencing tokens: monotonically increasing numbers issued with each lock acquisition. The protected storage system must reject operations with a token lower than the highest one it has already accepted. If a paused client resumes late, its stale token is rejected. Unlike the random ownership token from the previous post, a fencing token establishes the order of acquisitions and must be enforced by the protected resource.
Note: A monotonically increasing number is one that only ever goes up, never down. Each new value is strictly greater than all previous values (e.g., 1, 2, 3, …). This property is essential for fencing tokens because it allows the storage system to determine ordering: a higher token always means a more recent lock acquisition.
Examples of monotonic ordering mechanisms in distributed systems include:
- Lamport clocks: a simple logical clock that increments on each event
- Vector clocks: an extension that tracks causality across multiple nodes
- ZooKeeper’s zxid: a 64-bit transaction ID that increases with every state change
- Database sequences (e.g., PostgreSQL’s
SERIAL, MySQL’sAUTO_INCREMENT): centralized counters that guarantee uniqueness and ordering
Redis does have a counter command, INCR. The difficulty is guaranteeing that fencing tokens keep increasing across failures. With asynchronous replication, a primary can acknowledge an increment before a replica receives it. A failover can then lose that increment and allow an old counter value to be reused. Redlock’s random ownership tokens do not provide ordering either. A counter alone therefore does not resolve the fencing problem discussed here. These limitations make this Redis-based approach unsuitable when correctness requires reliable fencing across failures.
That said, for many applications where occasional race conditions are tolerable or where other safeguards exist (e.g., idempotent operations, database-level constraints), Redis locks, whether single-instance or Redlock, remain a practical and performant choice.
Alternative Solutions⌗
If you need strong consistency guarantees for distributed locking, consider these alternatives:
etcd: Provides a built-in lock API backed by leases. Fencing writes to external storage still requires the protected resource to check fencing tokens. Built on Raft, a consensus algorithm with formal correctness proofs, etcd guarantees linearizable operations across the cluster.
ZooKeeper: Offers distributed lock recipes using ephemeral sequential nodes. It uses
zxid(ZooKeeper Transaction ID) as a globally ordered, monotonically increasing counter that can serve as a fencing token. ZooKeeper uses the ZAB (ZooKeeper Atomic Broadcast) protocol for consensus.
Both systems are CP (Consistency + Partition tolerance) in CAP terms, sacrificing availability during network partitions to maintain strong consistency. This is the fundamental trade-off: Redis gives you speed and availability; etcd/ZooKeeper give you correctness guarantees.
References⌗
- Redis - Redis replication model
- How to do distributed locking - Martin Kleppmann’s critique of Redlock
- Is Redlock Safe? - antirez’s (the Redis creator’s) counterargument in favor of Redlock
- etcd - etcd Concurrency API
- ZooKeeper - ZooKeeper Locks Recipe
- Raft - The Raft Consensus Algorithm